


Platform editions
Cerebras
Ultra-fast cloud LLM inference powered by Cerebras Wafer-Scale Engine hardware.
Choose your platform
This add-on has separate macOS and Windows editions. Each page documents the features, settings, requirements, and screenshots for that platform.
macOS
v1.0.5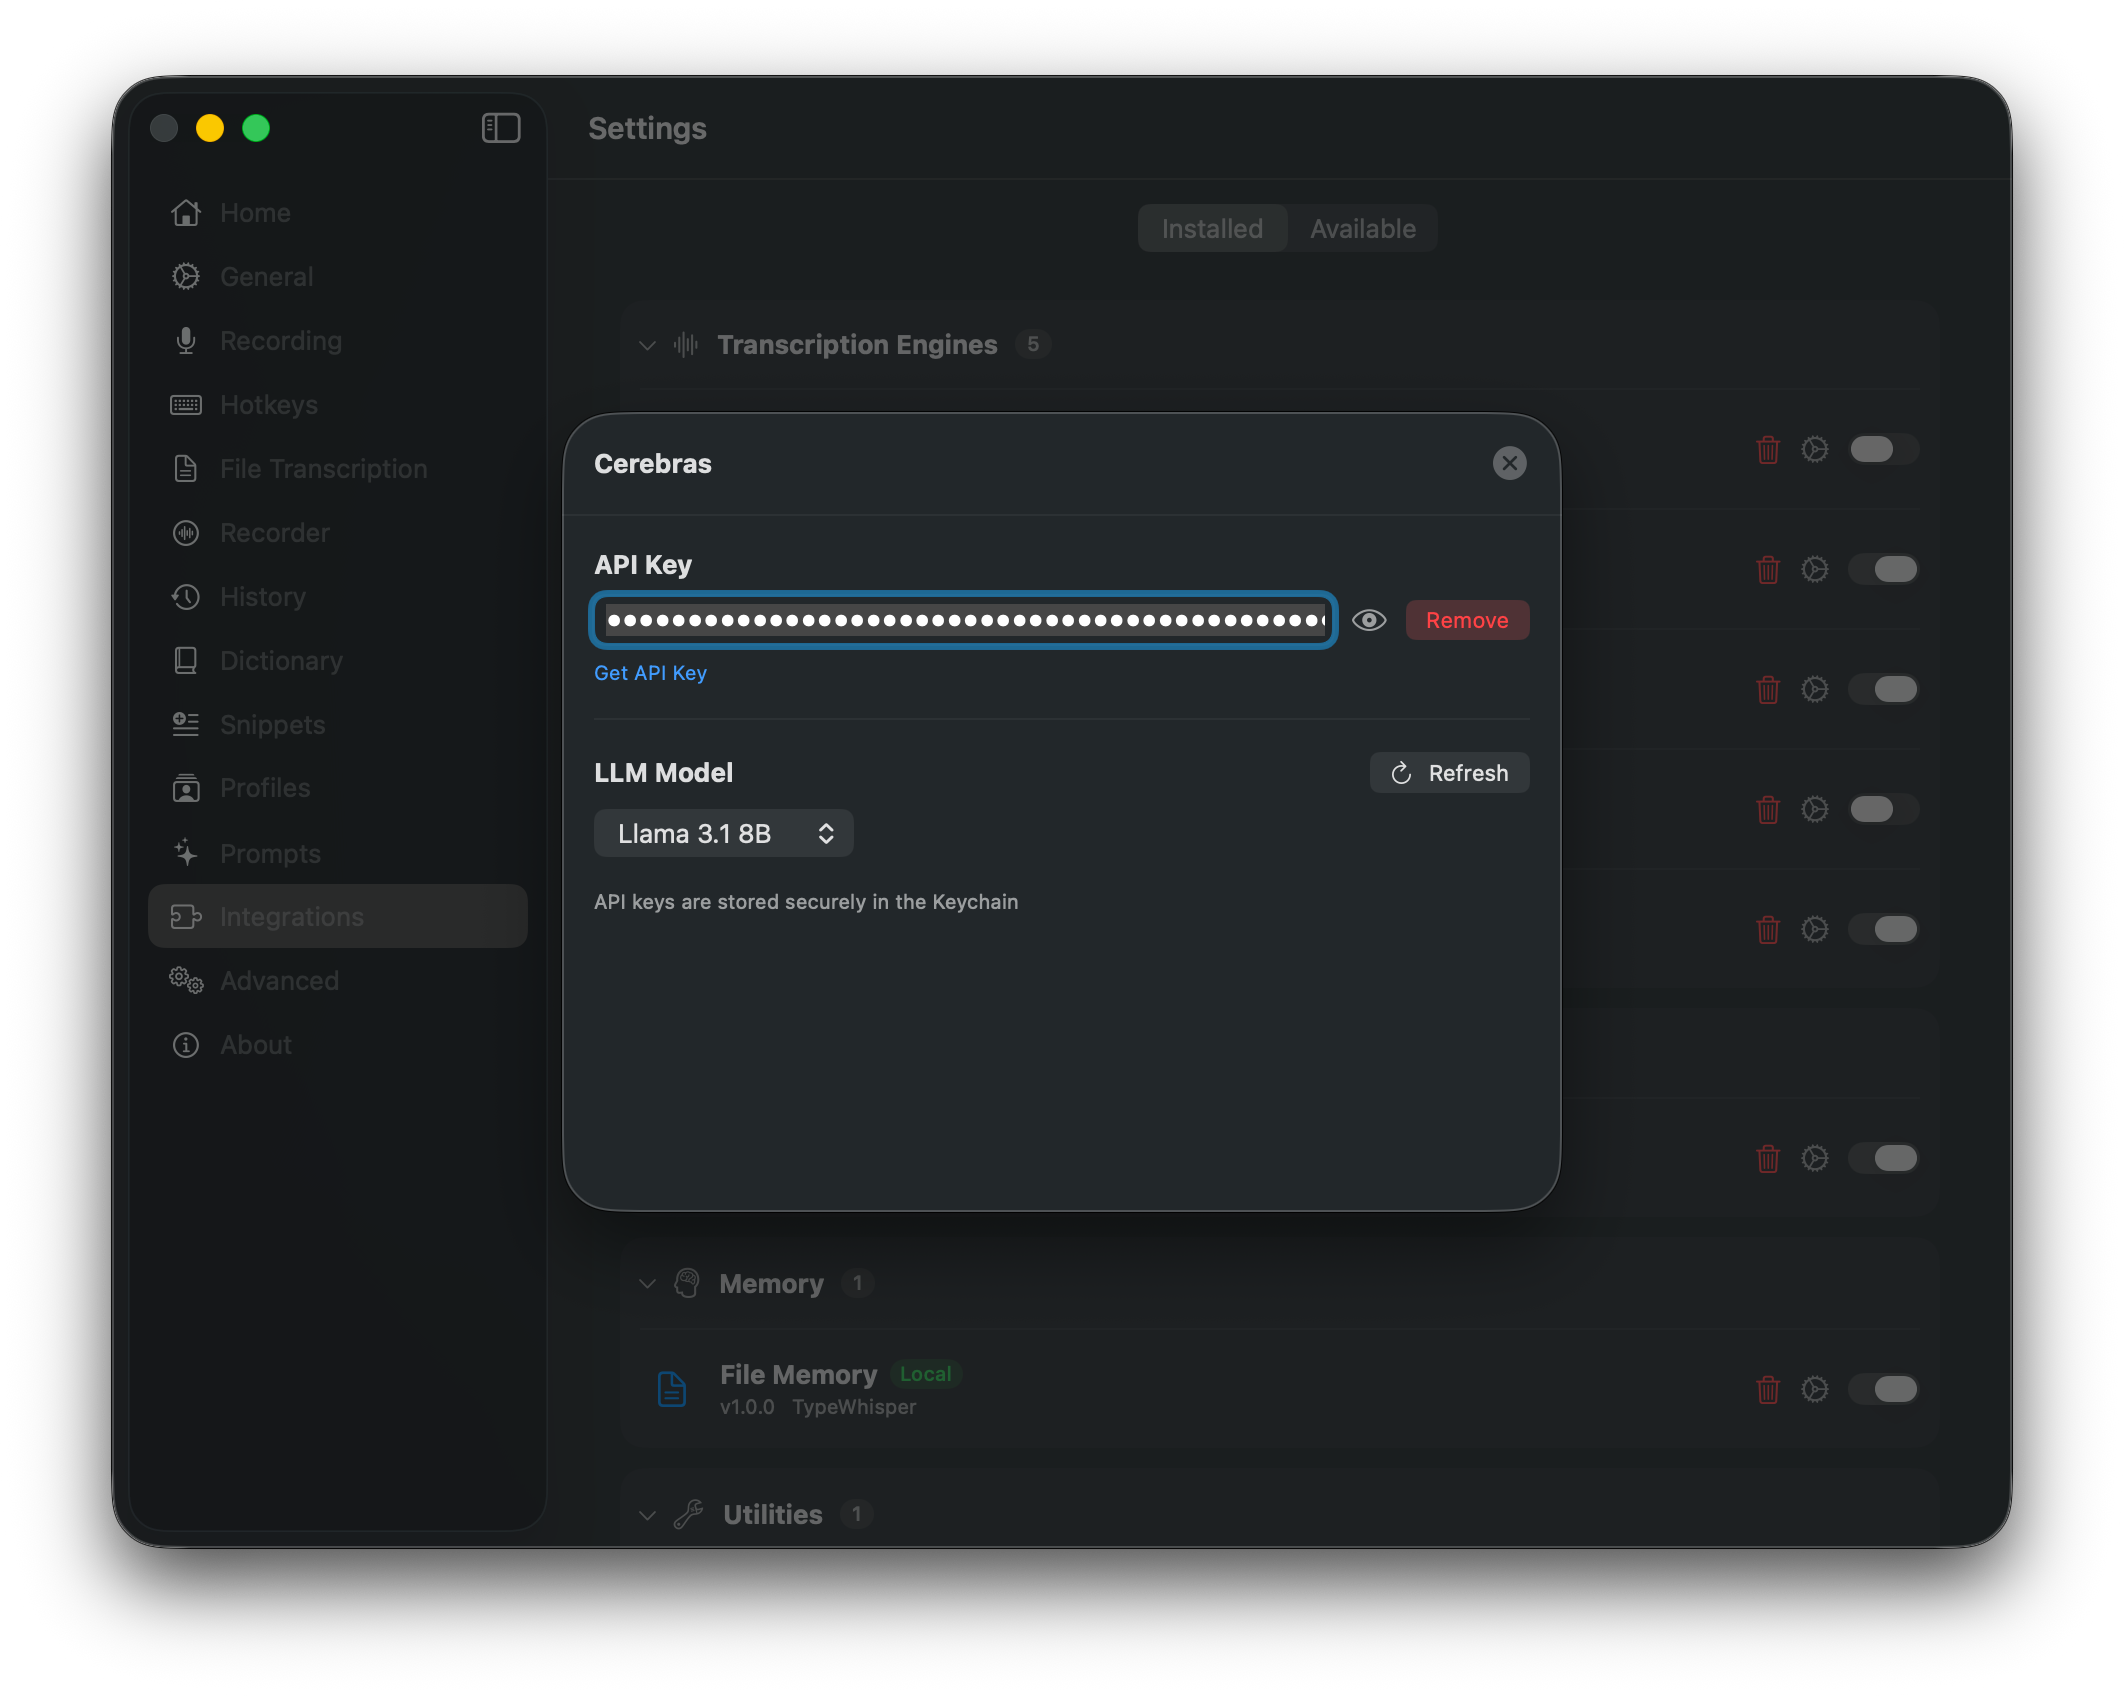
Cerebras as a fast cloud LLM provider with model selection and temperature controls.
- LLM provider for workflow prompts
- Selection or refresh of available models
- Provider-default or custom temperature controls
- Support for parallel hedged LLM requests
Windows
v1.1.2
Cerebras as a fast cloud LLM provider for workflow prompts, with model discovery and an optional sampling temperature.
- LLM provider for workflow prompts
- Starts with GPT-OSS 120B and Qwen 3.8 27B
- Loads the text models available to your Cerebras account
- Default text model, while a model set in the workflow takes precedence

