

Platform editions
Cerebras
Ultra-fast cloud LLM inference powered by Cerebras Wafer-Scale Engine hardware.
Choose your platform
This add-on has separate macOS and Windows editions. Each page documents the features, settings, requirements, and screenshots for that platform.
macOS
v1.0.5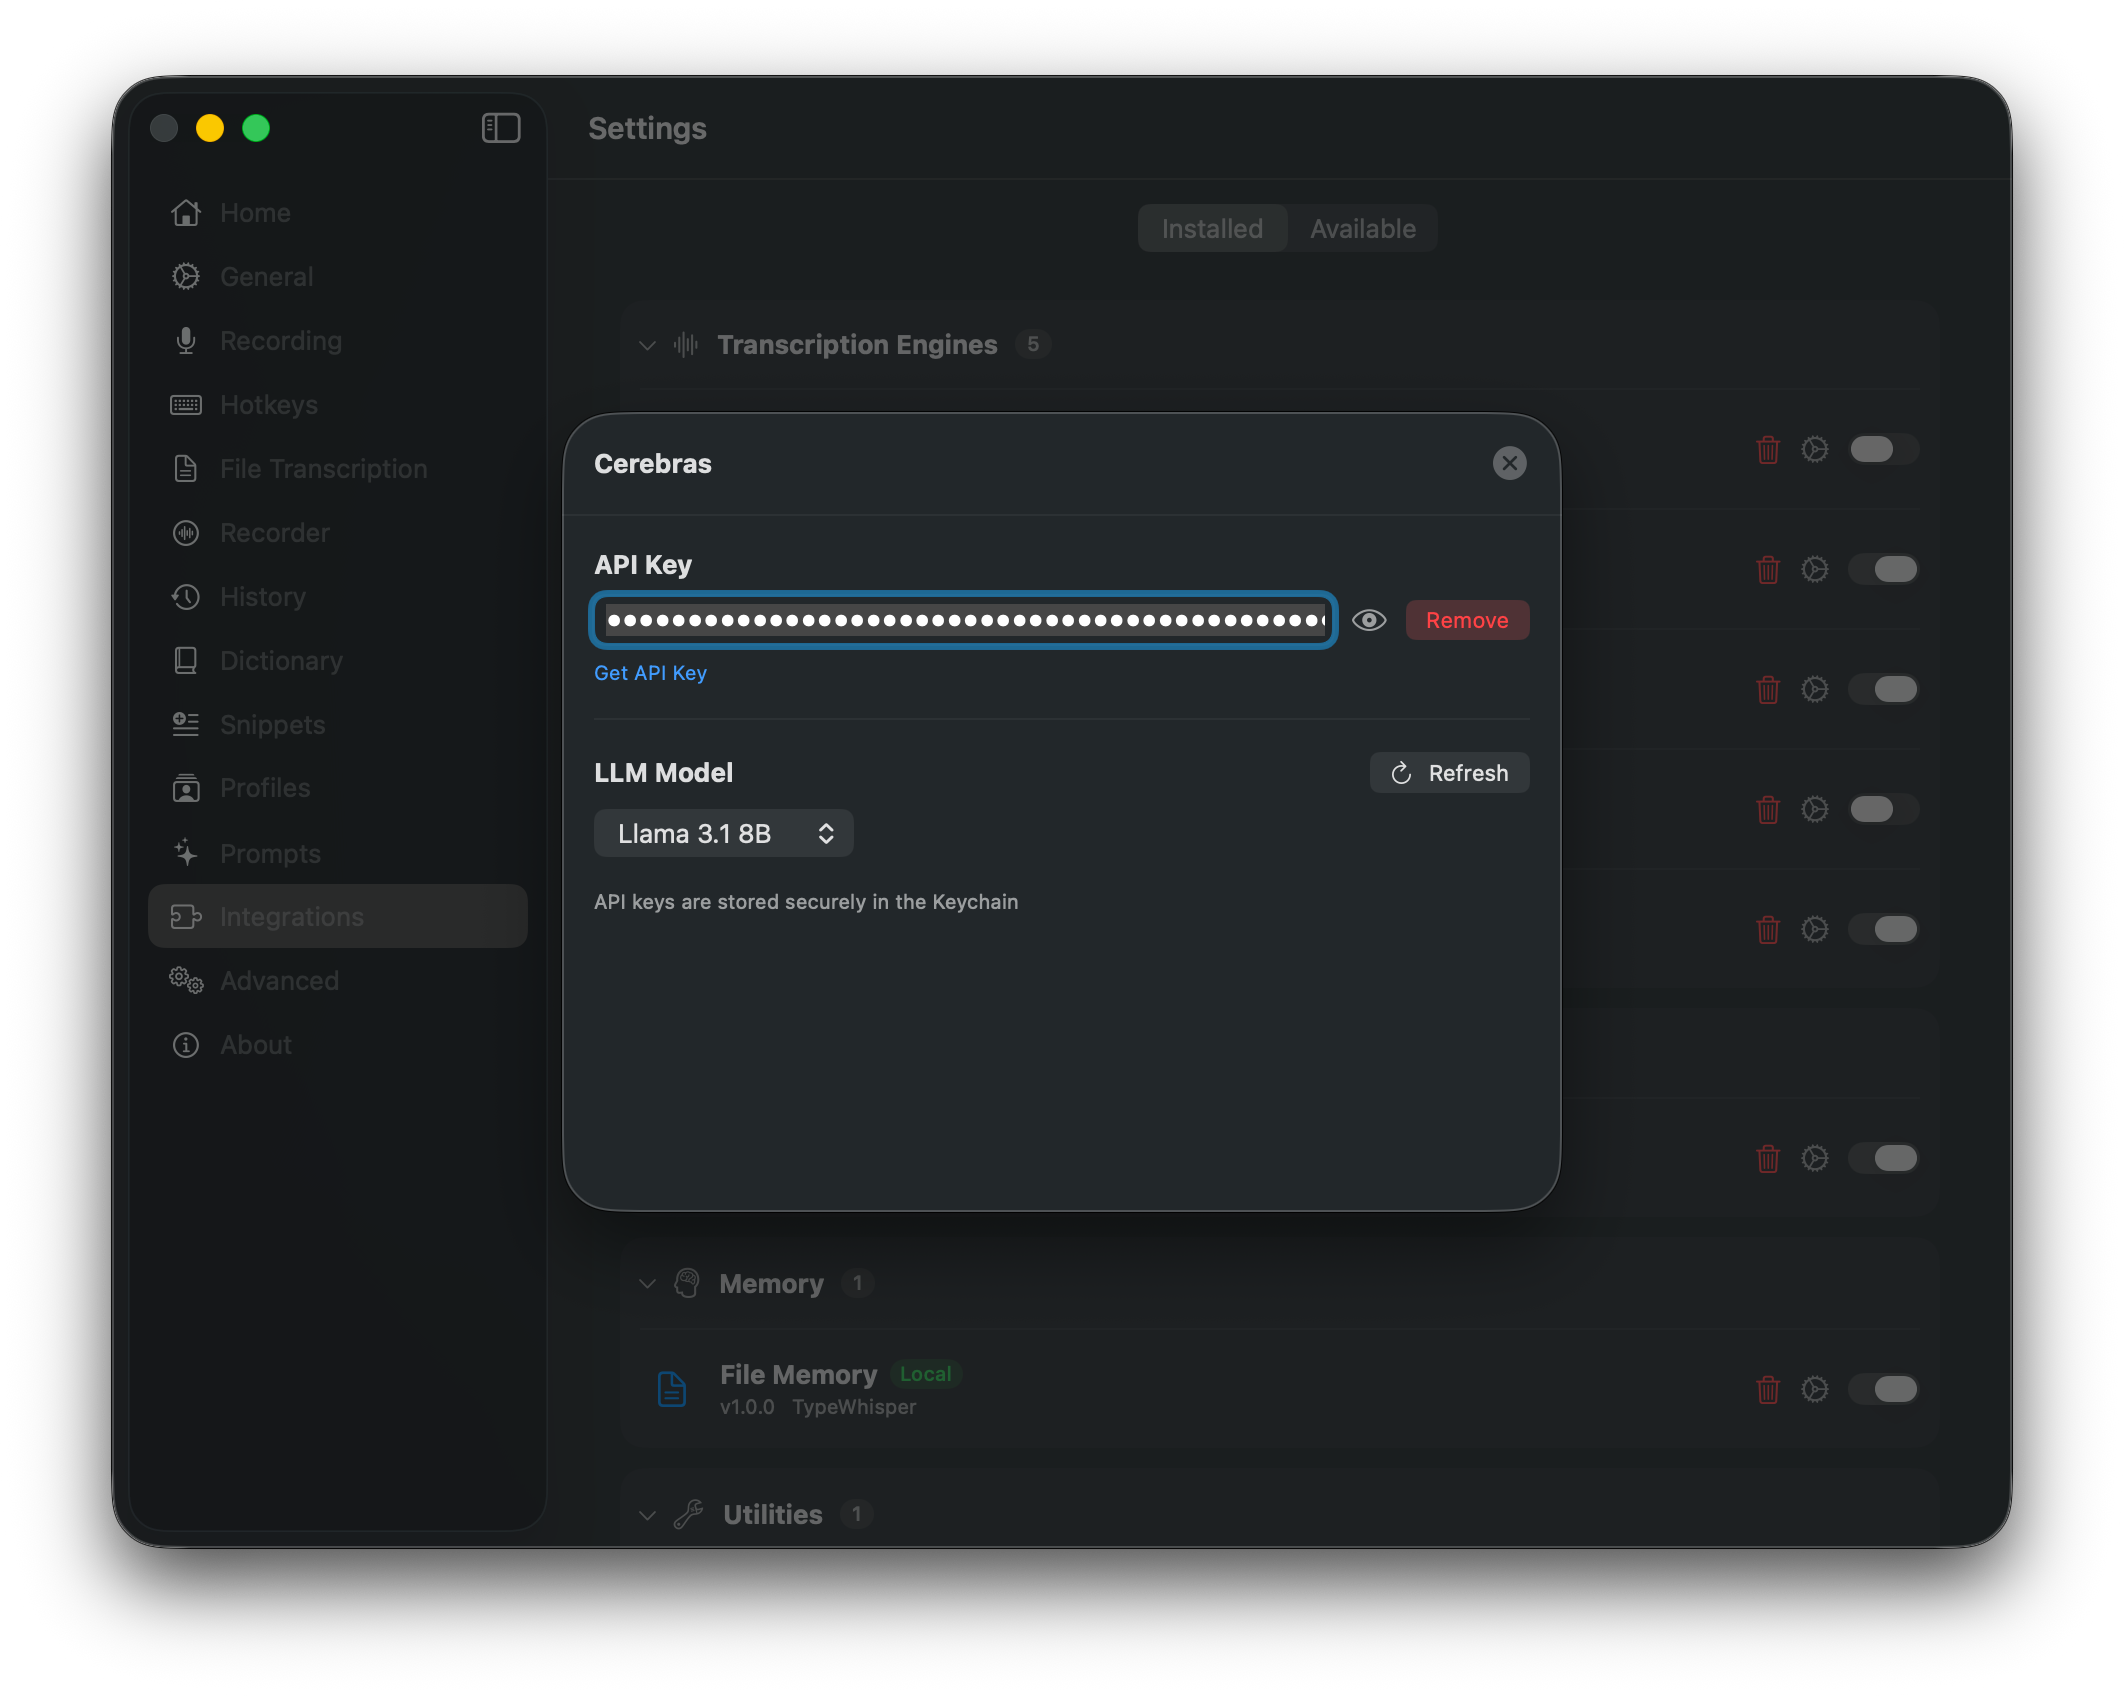
Cerebras as a fast cloud LLM provider with model selection and temperature controls.
- LLM provider for workflow prompts
- Selection or refresh of available models
- Provider-default or custom temperature controls
- Support for parallel hedged LLM requests
Windows
v1.0.0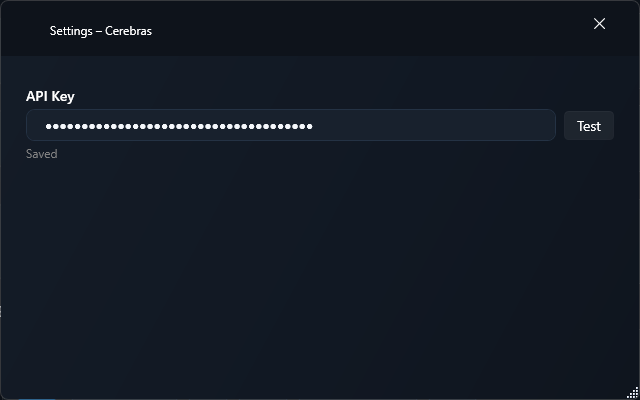
Cerebras as a fast cloud LLM provider for prompt processing.
- LLM provider for workflow prompts
- A built-in model selection
- Support for parallel hedged LLM requests
- Processing through the respective cloud provider

